NOTES · SCALE
Many rooms, one answer: how True Causes scales
True Causes runs Structured Democratic Dialogue online. A hall holds two hundred people; the internet has no hall, and fifteen people deliberating over the web is not the hard part: Structured Democratic Dialogue has done that for years. The hard part is forty rooms of fifteen working the same question and ending with one answer — then four thousand, with no one's load growing. That needs four things: knowing when two groups said the same thing, carrying a claim two groups raised to the few groups most likely to judge it, sending a deadlock where it can be settled, and folding every local map into one. The method's own recent work comes closest to the last: asynchronous individual maps used to extend a session's map (Laouris, 2023), and thematic maps merged in a final session of their authors (Michaelides & Laouris, 2024). What had not been built is doing it for thousands of rooms, with no session to merge them. What it amounts to is collective intelligence without a committee: nobody holds the whole map, and nobody has to.
Three things bind a co-laboratory to its venue: everyone reads the same wall, one facilitator holds every thread, and the room decides what a claim means. Each has a counterpart here that does not need the room. A facilitator is welcome in any room; what changes is that the method no longer depends on one being there.
Every group gets its own wall
Participants work in small groups — small enough that everyone reads the whole wall. Once a room grows past that, it is split into groups, each with its own wall, and the room's map holds them all. Nobody's load grows with the room: one person's work is the same whether the question has fifteen participants or two million.
The same question, wherever it is asked
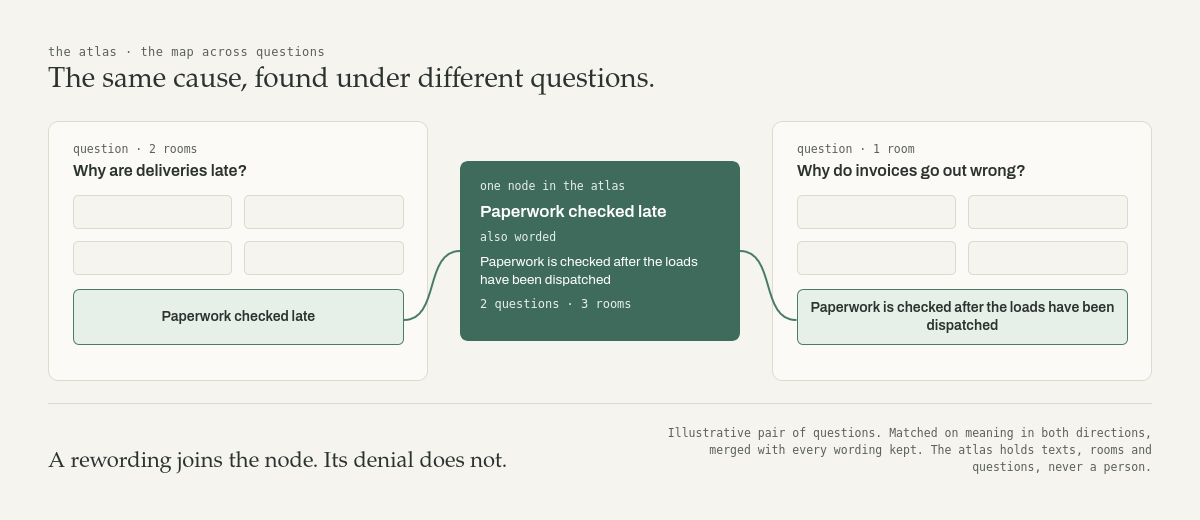
A room is not the unit — the question is. Open a dialogue and the platform recognises other rooms already asking it, however differently worded, and joins them into one deliberation. Their groups become groups of the same question, and claims move between all of them.
A few ideas travel; people don't
The same claim written in two groups is counted as one claim raised by two groups. That single choice is what makes scale computable: without it, a claim in forty rooms is forty items and nothing can be counted at all. Between rooms, a few cards travel — after a room has finished generating and before it starts clarifying, so nothing arrives while people are still thinking for themselves. Only a select few travel, chosen to be diverse, so a wall stays a wall whatever the number of rooms. They arrive with their author's clarification, as ordinary cards, and are judged like any other. A private room can ask for this one way: the cards from listed rooms on its question still arrive on its walls, and nothing of its own goes out.
How two wordings become one claim
Counting groups only means something if you can tell when two of them said the same thing in different words. The platform spots the likely pairs and puts them to the people who wrote them. It never merges anything itself: two members have to agree that two wordings are one claim, and either can take it back.
The asymmetry is deliberate. A false merge is the costly mistake — fold a claim into a popular one and it inherits that support — while a missed merge only costs a little efficiency, since the claim still travels as two items instead of one. Claims that contradict or reverse each other are never offered as the same claim, however similar they look.
Every group's map becomes one map
Each group structures the wall it actually deliberated on and produces its own map. Those maps are then folded together: the same claim is one node, every connection carries how many groups certified it independently, feedback loops collapse into single deep causes, and roots are read off the merged graph. Where groups of one room certified opposite things, the contradiction is published as a conflict and referred, like any deadlock, to two other groups that must agree. Across rooms, each room’s finding stands, and the link shows how many of the rooms that judged it found it: a cause can hold in one place and not in another. Nothing is averaged away.
Collective intelligence in every room, a swarm across them
Each room is collective intelligence on its own: people who clarify, discuss and judge together. Its thinking is spread across its people, its wall and its map, what researchers call distributed cognition. Between rooms, the platform adds a swarm. In the swarms people know from nature and from software, each member follows the trail the others left: ants reinforce the path most ants took, and in a live human swarm everyone watches the group pull. That is how a swarm converges, and it is also how a crowd herds. Here the rooms do not follow each other. A room writes before anything arrives, judges its pairs without seeing how other rooms judged them, and one organisation counts as one voice however many rooms it opens. So when many rooms certify the same link, they found it separately, and the count means something. Agreement is evidence only as far as the sources were independent, which is the point social epistemology makes about testimony. The swarm is in the structure: no room holds the whole problem, the cards that travel are few and chosen to be diverse, and the map that comes out holds links no single room could have drawn.
Why small groups. Below about a dozen people, a panel starts losing causes; above the size a person can read as one wall and follow as one conversation, it gains nothing — the size the method's practitioners settled on across a hundred and twenty dialogues. So scale comes from more groups, not bigger ones.
Where a deadlock goes. Not back to the group that split, and not to everyone. The question is referred to two other whole groups, chosen in a way nobody can steer toward a friendly audience. Each answers on its own, and they have to agree — if they don't, the pair is published as contested. One group is never enough: in simulation a single referral hands back a wrong answer 29.6% of the time when a bloc is voting, where two or more does not.
What coordinated voting achieves. Three of a group's fifteen seats, a fifth of the group, voting together against one cause hold it to 40% of where it should be, and touch nothing else. Referral to other groups takes it back to 62%. The rest is closed by seats — a way onto the shortlist that does not run through the people trying to keep it off. Piling votes onto the ballot alone does nothing the seats do not fix.
No model decides anything. A language model is used in one place — reading a plain-language argument into premises so the logic check can run — and it is forbidden to judge whether the argument is valid; a fixed engine does that. Deciding that two claims are the same is left to people.
Support has to be earned. A link counts as found by several rooms only when those rooms are really separate: rooms that stand on one source, or vote as one, count once. In simulation, five fabricated rooms against five real ones took a real cause off the shared map in 31% of runs; with this rule the cause survived in every run.